Computer vision lets machines interpret images and video: reading number plates, spotting defects on a production line, helping radiologists review scans. Models are now very capable, but taking them from a demo to a dependable system is hard. This guide covers the six most common challenges in computer vision, and practical ways to deal with each.
Key takeaways
- Data is the biggest challenge: quantity, quality, labelling and variety all matter.
- Models can fail on conditions they have not seen, such as odd lighting or new camera angles.
- Explainability, privacy and bias need attention from the start, especially for people-related uses.
- Plan for deployment, monitoring and retraining, not only the model.
What computer vision is used for
- Quality inspection in factories and detecting defects.
- Medical imaging support, such as flagging suspicious regions on scans.
- Retail and warehouse analytics, shelf checks and inventory counting.
- Document reading, including the OCR step in intelligent document automation.
- Vehicles and robots that need to perceive their surroundings; see cobots.
Here is a short video introduction to the field:
1. Data: quantity, quality and labels
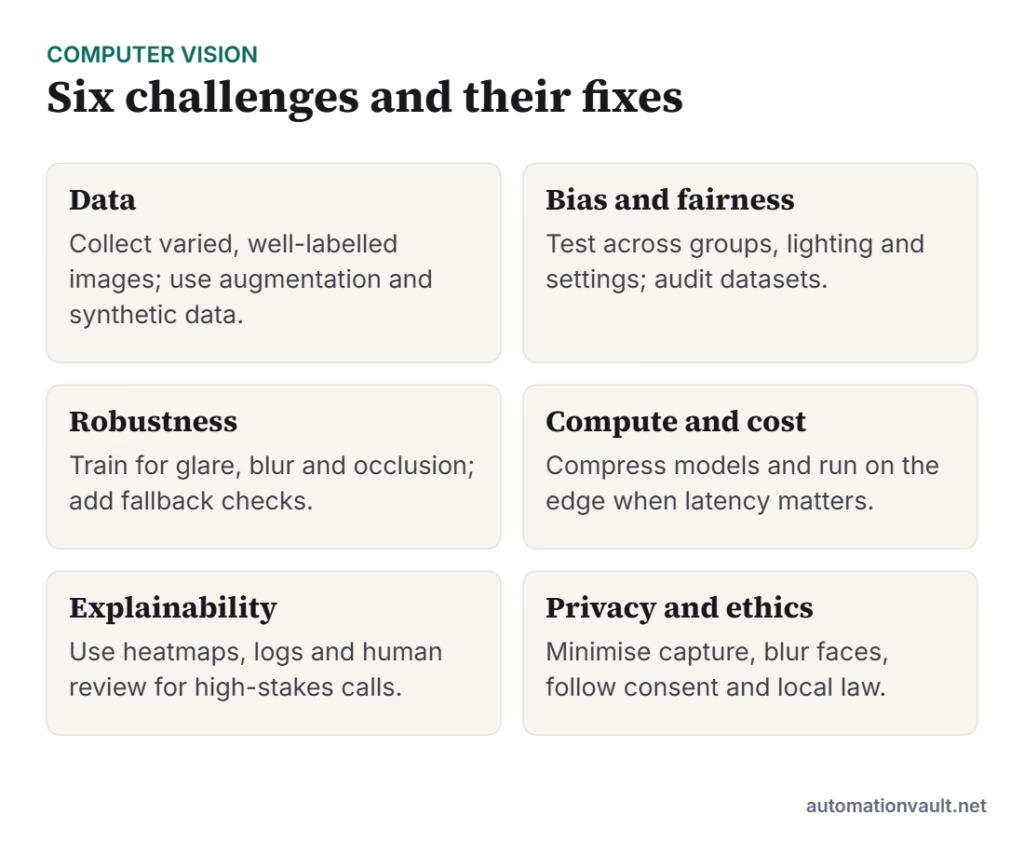
Most vision systems are only as good as their training data. Good models need many examples that cover real conditions, correctly labelled. Collecting and labelling data is slow and expensive, and rare events (a defect that appears once in 10,000 items) are hard to capture.
- Use data augmentation (flips, crops, brightness changes) to stretch your dataset.
- Use synthetic or simulated images for rare cases.
- Use pre-trained models and fine-tune them with fewer examples.
- Invest in labelling guidelines and quality checks.
2. Bias and fairness
If training data lacks variety, the model performs worse on groups, environments or objects it saw less often. Face analysis tools, for example, have shown different error rates across demographic groups. Test performance on separate subgroups and settings, and document known limits before deployment.
3. Robustness in the real world
A model that works in the lab may fail with glare, rain, motion blur, partial occlusion or a camera moved a few degrees. Models can also be fooled by deliberately altered images, known as adversarial examples. Train and test on messy real-world images, monitor performance in production and add fallbacks, such as asking a person to check when confidence is low.
4. Compute, cost and deployment
Large vision models need significant computing power, and many applications need results in milliseconds on small devices. Options include compressing or distilling models, running them on edge devices close to the camera, and processing only frames that change. Deployment also needs version control, monitoring for drift and a plan for retraining; see AI in Industry 4.0 for factory examples.
5. Explainability
Deep neural networks are hard to interpret, which is a problem when a decision affects a person’s health, safety or rights. Techniques such as heatmaps show which image regions influenced a result, but they do not fully explain it. For high-stakes uses, keep a qualified person in the loop and record inputs and outputs for audit.
6. Privacy and ethics
Cameras capture people. Collect only what you need, tell people when and why, blur faces where possible and limit how long footage is kept. Rules differ by country, and facial recognition in particular is restricted or regulated in many places. Involve legal and privacy teams early.
A checklist before you deploy
- Is the training data representative of real conditions?
- Have we tested on edge cases and different groups?
- What happens when the model is unsure?
- Who monitors accuracy after launch, and how often is it retrained?
- Have privacy, safety and legal reviews been completed?
For a broader view of AI fields, see the main branches of AI.
Frequently asked questions
What is the biggest challenge in computer vision?
Usually data: getting enough varied, correctly labelled examples that match real conditions. Many failures in production trace back to data gaps.
Can computer vision work without much data?
Often yes, by fine-tuning a pre-trained model, using augmentation and adding synthetic examples. The more specialised your task, the more of your own data you will need.
Is computer vision accurate enough for medical or safety uses?
In many narrow tasks it can match or support experts, but it should be validated, regulated where required and used with human oversight.
Leave a Reply